

Run open decision models locally, the way Ollama runs LLMs.
Website · Models · Bench · Docs · Releases · Hugging Face
Created and maintained by Mert Cobanov (@mertcobanov).
A decision model reads a state (a message, an email, a ticket, any JSON) plus typed questions
(choice, score, noul) and returns calibrated probabilities in a single forward pass, in
milliseconds. It never generates text. Ollaya pulls these models by name, serves them from a
local daemon, and speaks TypeSafe's /v1/systemone wire format, so existing Jev clients work by
changing one environment variable.
curl -fsSL https://ollaya.dev/install.sh | sh
ollaya run winnow:e4b --preset triage "Third time this year you've double-charged me. Refund it today or I'm cancelling and moving to a competitor."
intent refund ███████████████░ 0.91
is_urgent yes ███████████████░ 0.92
frustration 2.89 / 3 very angry or using stron… ██████████████░░ 0.86
refund_requested yes ████████████████ 0.99
churn_risk yes ████████████████ 0.99
Or ask your own questions: ollaya run kev --ask "Is a refund requested?" --ask "Which team?" --choice billing --choice sales < ticket.txt.
winnow:e4b is the recommended model: 0.724 accuracy on typed decisions (TypeSafe reports 0.738 for its Jev) and 113 ms for five questions on an RTX 5090. It is a 4B-class language model, so without an NVIDIA GPU start with laya: laya:multilingual answers five questions in 516 ms on a CPU. All models and their numbers: ollaya.dev/search.
- One binary.
ollaya serveruns the daemon;ollaya run,pull,list,ps,show,rm,cp,stopandcreatework the way they do in Ollama. If the daemon isn't running, the CLI starts it. - TypeSafe-compatible.
POST /v1/systemone,/v1/decisionsandGET /v1/modelsare wire-identical to TypeSafe. The official SDK works unchanged when you setTYPESAFE_BASE_URL=http://localhost:11435. - Native API.
/api/decideadds routing information and timings./api/pullstreams NDJSON progress, and there are/api/tags,/api/show,/api/psand more. See docs/api.md. - Weights come from their authors. Ollaya publishes only small ONNX graphs, about 3 MB each.
These graphs read the original weight files (usually
model.safetensors) from the author's Hugging Face repository, pinned to a commit and verified by sha256. Models whose authors publish GGUF files (winnow,jevk5,jeb) run that file itself on llama.cpp. Ollaya never re-hosts weights. - For agents.
ollaya mcpserves the models to Claude Code, Claude Desktop, Cursor and other MCP clients (claude mcp add ollaya -- ollaya mcp), and theollaya-decisionsskill teaches agents when and how to use them (npx skills add ollaya-dev/ollaya --skill ollaya-decisions). - Routers.
layadetects the script and language of each request, then answers withlaya:enorlaya:multilingual. - Modelfiles. You can bake a question set into your own model:
Then run
FROM laya QUESTIONS ./triage.json PARAMETER precision fp32ollaya create triage -f Modelfileandollaya run triage "…". - Fast and exact.
- Hardware: ONNX Runtime on CPU, and CUDA on NVIDIA GPUs. GGUF models run on llama.cpp: CPU, ROCm/HIP on AMD GPUs, Vulkan on Windows (any vendor's GPU; an integrated one when you name it), CUDA on NVIDIA GPUs, and Metal on Apple silicon.
- Precision: ONNX uses fp16 on GPU and fp32 on CPU when available; GGUF keeps its model quantization on either device.
- Accuracy: fp32 exports give the same decision as the PyTorch reference on 100% of 2,383 questions per checkpoint.
| Model | What it is |
|---|---|
winnow:e4b |
Recommended. EldanRing's Winnow-E4B, a Gemma 4 fine-tune run from the author's Q8_0 GGUF on llama.cpp |
credence:e4b, credence:e4b-calibrated |
Txoka's MiCA refinements of Winnow-E4B, Q8_0: accuracy-focused and public-calibration variants; see the measured tradeoffs in the family documentation |
laya |
Router: picks laya:en or laya:multilingual by language |
laya:en |
English decision model (ModernBERT-large, 421M) |
laya:multilingual |
100+ languages (mmBERT-base, 322M) |
laya:typed-decisions |
Fine-tuned on the typed-decisions workflows |
decider, decider:4b, decider:0.8b |
Mapika's Qwen3.5 decoders, 2B (the default), 4B and 0.8B |
decider:2b-vision |
Mapika's Qwen3.5-2B vision-language decider: questions about an image (--image, images on /api/decide) as well as the state |
kev, kev:0.8b, kev:9b |
Jared Palmer's Kev: a LoRA and a pointer head on Qwen3.5 (4B by default, 0.8B, 9B), calibrated |
decision |
Decision 1.0 Eos by the vLLM Semantic Router contributors: a fine-tuned Qwen3.5-0.8B with an endpoint head, 16k-token rows |
qwen3guard |
Qwen3Guard-Gen-0.6B safety guard with built-in questions: safe, controversial or unsafe, and the category |
nli, nli:modernbert-large |
Moritz Laurer's zero-shot NLI classifiers (DeBERTa-v3-large, ModernBERT-large) |
gliclass |
Knowledgator's instruction-following zero-shot classifier (DeBERTa-v3-large) |
von |
Victor Hugo Panisa's Von 1.1 (ModernBERT-large): every option scored at its own marker, 8k-token context |
winnow |
EldanRing's Winnow-12B, the larger sibling of winnow:e4b |
clm |
Contrastive-LM's CLM-v0.1-8B: the Qwen3-8B encoder and two projection heads score options by similarity, with questions and options cached. Built for agent, game and tool-calling states |
jevk5 |
alibiserikbay's JevK5 v0.3, a Qwen3.5-4B fine-tune run from the author's Q8_0 GGUF on llama.cpp, up to 16 options |
nimble, nimble:9b-v3 |
Bespoke Labs' Nimble v2: a LoRA on Qwen3.5-9B that reads the whole request as a JSON schema and scores option codes, with the author's temperature, up to 255 options. nimble:9b-v3 is v3 (non-commercial license) as the author's Decision Index engine serves it |
strands-decider |
Strands Agents' Strands Decider: a LoRA and a pointer head on Qwen3.5-2B base, every option scored at the end of its own line, calibrated per question type; up to 255 options |
pplx-decider |
Perplexity's pplx-decider-flash v1.2: Qwen3.5-4B distilled from its 27B decision models, every question in one sequence and read at its own marker, calibrated; up to 255 options |
jeb, jeb:4b, jeb:27b |
Jason Brashear's Jebadiah (AINode): LoRAs merged into Qwen3.5 (9B by default, 4B) and Qwen3.8-27B, run from the authors' GGUF on llama.cpp with their per-type temperatures |
jeeves |
PostHog's Jeeves-9B without its reasoning chain: Qwen3.5-9B (LoRA merged) and a pointer head |
clef |
Cloudflare's Clef-Flash: Qwen3.5-9B, fully post-trained, with a joint schema head that scores every question's options in one forward pass, with no fitted temperature |
cygnet |
blockbrain-ai's Cygnet: frozen Gemma 4 12B IT (Q8_0 GGUF) with a letter-readout prompt and temperature 3.4 |
snap |
logitlab's snap1-2b: MiniCPM5-2B fine-tuned on the prompt of emnlmn's snap engine, run from the author's Q8_0 GGUF on llama.cpp with snap's own prompt, up to 26 options |
d1, d1:3b-vision |
Liquid AI's d1-3B, on LFM2.5-VL-3B: typed text and image decisions from the author's Q8_0 GGUF and projector, with max-pooled answer forms and temperature 1.0 |
decima, decima:agent, decima:small |
A. M. Madani's Decima: multilingual encoders with a late-interaction scorer that reads every option against the state. decima:base is mmBERT-base (321M); decima:agent (2.2) is fine-tuned for coding-agent decisions and knowledge-graph judgments; decima:small (122M) is the smallest |
largha |
Phocinae's Largha: Laya's decision network on mmBERT-small (144M), fine-tuned on the typed-decisions workflows; runs on the CPU, CUDA and the Apple GPU |
arbiter |
Codekins' Arbiter v3.3 (Zyot Lab): a LoRA and a fixed 24-slot head on Gemma 3 4B IT, one forward pass per question. It answers noul, choices of up to 16 options and scores of exactly 6 levels |
Browse them at ollaya.dev/search; every tag's accuracy, speed and memory is on
Ollaya Bench. Decoder tags ending in -fp16 (kev:4b-fp16) compute in fp16 on NVIDIA
GPUs: faster, with at least 99.5 % of their decisions the same as the base tag's. Laya's -fp32 and -fp16 tags
pin the precision. The derived files of every model are also published at
huggingface.co/ollaya-dev.
Ollama 0.40 also serves decision models, nine of them, through the same TypeSafe wire format (measured side by side). The FAQ compares the two projects.
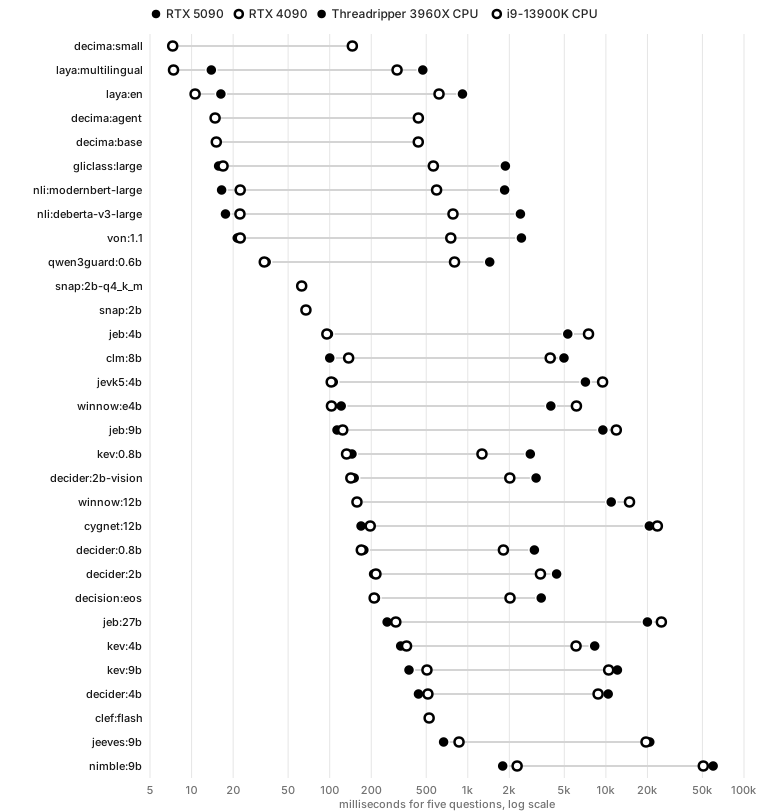
Every model in the library is measured on our own machines and published, with the raw data, on Ollaya Bench: one released runtime, each author's own weights, the same 5,880 questions for every model (Bespoke Labs' 13 public subsets and typed-decisions), and speed and memory on a GPU and a CPU.
Edition 2026.10 ran Ollaya 0.13.0 on an RTX 5090 desktop, and 0.14.0 and 0.15.0 added what they changed:
- Score. Chance-corrected accuracy over 14 tasks, with 95 % intervals:
pplx-decider:flash73.7,jeb:27b67.8 (scored without typed-decisions, which it was trained on),winnow:12b65.7,clef:flash65.1 andjeb:9b64.9 (scored without typed-decisions, which it was trained on). The fastest of these,jeb:9b, answers five questions in 107 ms on the RTX 5090. - Calibration. The lowest calibration errors on the public benchmark are 0.016 (
pplx-decider:flash), 0.022 (laya:typed-decisions,nimble:9b) and 0.024 (jeb:27b). - Speed and memory. Five-question requests through the HTTP API take 14 ms to 1.0 s on the RTX 5090 and 339 ms to 62.0 s on its Threadripper 3960X. Every model's VRAM and RAM are on its page.
- Parity. Before a model ships, its runtime is checked question by question against the authors' code (or llama.cpp's own server, for GGUF models) on each device it runs on.
Earlier runs, the comparison with Ollama on the same GPU (on the same Nimble weights the calibration error is 0.022 on Ollaya and 0.115 on Ollama) and the Windows, CUDA and Vulkan measurements are at ollaya.dev/results.
- Linux (x86_64 or arm64, glibc ≥ 2.38, e.g. Ubuntu 24.04+):
curl -fsSL https://ollaya.dev/install.sh | sh. When an NVIDIA GPU is present (driver R525+), the installer adds the CUDA runtime: CUDA 13 for R580+, CUDA 12 for older drivers. - macOS (Apple silicon): the same command.
- Windows (x64):
irm https://ollaya.dev/install.ps1 | iexin PowerShell. When an NVIDIA GPU is present (driver R527+), the installer adds the CUDA runtime, as on Linux. - Desktop app for macOS, Windows and Linux: start and stop the server, download models and run them in one window. On macOS it lives in the menu bar. Get it from ollaya.dev/download.
- Docker:
docker run -d --gpus=all -p 11435:11435 ghcr.io/ollaya-dev/ollaya:cuda(:cuda12for host drivers older than R580), orghcr.io/ollaya-dev/ollayafor CPU only.
Configuration is through environment variables: OLLAYA_HOST, OLLAYA_MODELS,
OLLAYA_KEEP_ALIVE, OLLAYA_DEVICE, OLLAYA_API_KEY and others, listed in
docs/api.md §15.
| Path | What |
|---|---|
crates/ollaya |
The binary: CLI, daemon, runner |
crates/ollaya-server |
HTTP API, scheduler (one runner process per model), model resolution |
crates/ollaya-api |
API types and client; the contract is docs/api.md |
crates/ollaya-registry |
Model names, manifests, blob store, resumable pulls |
crates/ollaya-decision |
Question schema, sequence layouts, calibration, answers |
crates/ollaya-runner |
Inference engines (ONNX Runtime, and llama.cpp for GGUF models) |
crates/ollaya-lang |
Script and language detection for routers |
convert/ |
Build-time Python: ONNX export, parity checks, packaging |
site/ |
The website and the static model registry host |
cargo test --workspace
cargo build --release -p ollaya --features cuda   # CUDA build (x86-64 Linux and Windows)
convert/ rebuilds models. It exports them, checks parity against the PyTorch reference,
generates golden fixtures, and packages the result into registry/. See the module docstrings.
cd convert && uv sync installs it: with CUDA 13 torch on Linux and Windows, and with the CPU and
MPS build from PyPI on Apple silicon Macs, where exports and parity run on the CPU.
Apache-2.0. Each model keeps its own license: laya (Convai Innovations), decider (Mapika),
kev (Jared Palmer, on Qwen3.5 by the Qwen team), decision (the vLLM Semantic Router
contributors, on Qwen3.5), qwen3guard (Qwen team), gliclass (Knowledgator), von (Victor Hugo
Panisa), winnow (EldanRing, on Gemma 4 by Google DeepMind), jevk5 (alibiserikbay, on Qwen3.5), nimble
(Bespoke Labs, on Qwen3.5), pplx-decider (Perplexity, on Qwen3.5), strands-decider (Strands Agents, on Qwen3.5), jeeves (PostHog, on Qwen3.5), clef (Cloudflare, on Qwen3.5), jeb (Jason Brashear, on Qwen3.5 and Qwen3.8), cygnet (Gemma 4 by Google
DeepMind; the Cygnet recipe is MIT), snap (logitlab, on MiniCPM5 by OpenBMB; snap's prompt is MIT), decima (A. M. Madani, on mmBERT-base by JHU CLSP and multilingual-e5-small by intfloat, both MIT), largha (Phocinae, on mmBERT-small by JHU CLSP, MIT) and nli:modernbert-large are Apache-2.0, and nli:deberta-v3-large (Moritz Laurer) is MIT. arbiter's LoRA adapter and head (Codekins Pvt Ltd, Zyot Lab) are Apache-2.0; its base model, Gemma 3 4B IT by Google DeepMind, is under the Gemma Terms of Use. nimble:9b-v3's adapter (Bespoke Labs) is CC BY-NC 4.0, which does not allow commercial use; its base, Qwen3.5-9B, is Apache-2.0. d1 (Liquid AI) is under the LFM Open License v1.0: commercial use by an organization with US$10 million or more in annual revenue is not covered by it. llama.cpp, which Ollaya ships for
GGUF models, is MIT.
Ollaya is an independent project. It is not affiliated with or endorsed by Ollama or TypeSafe.